Turn PDF Documents Into
Structured Data
PyMuPDF is the fast, lightweight Python library for PDF processing, built for AI applications, search, extraction, automation, and more.
Structure-Aware Analysis,
Now Part of PyMuPDF
PyMuPDF 2.0 brings PyMuPDF, PyMuPDF4LLM, and Layout together. That means structure-aware document parsing is now part of the main PyMuPDF package instead of requiring a separate package.
Grounding in Document Extraction
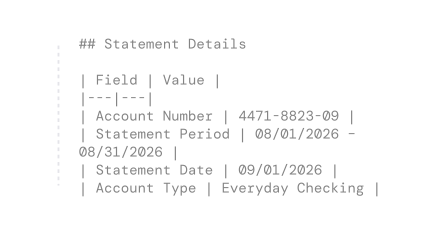
Ground AI answers in the original document, so you can trust the results, trace their sources, and verify the evidence.
- Preserve the structure and relationships within the original document.
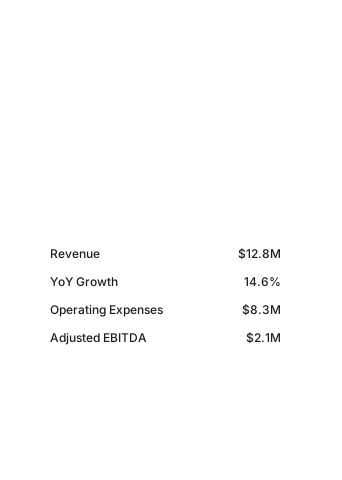
- Connect content to its exact source location, from text blocks to table cells.
- Give AI results the context needed to reference and validate sources.
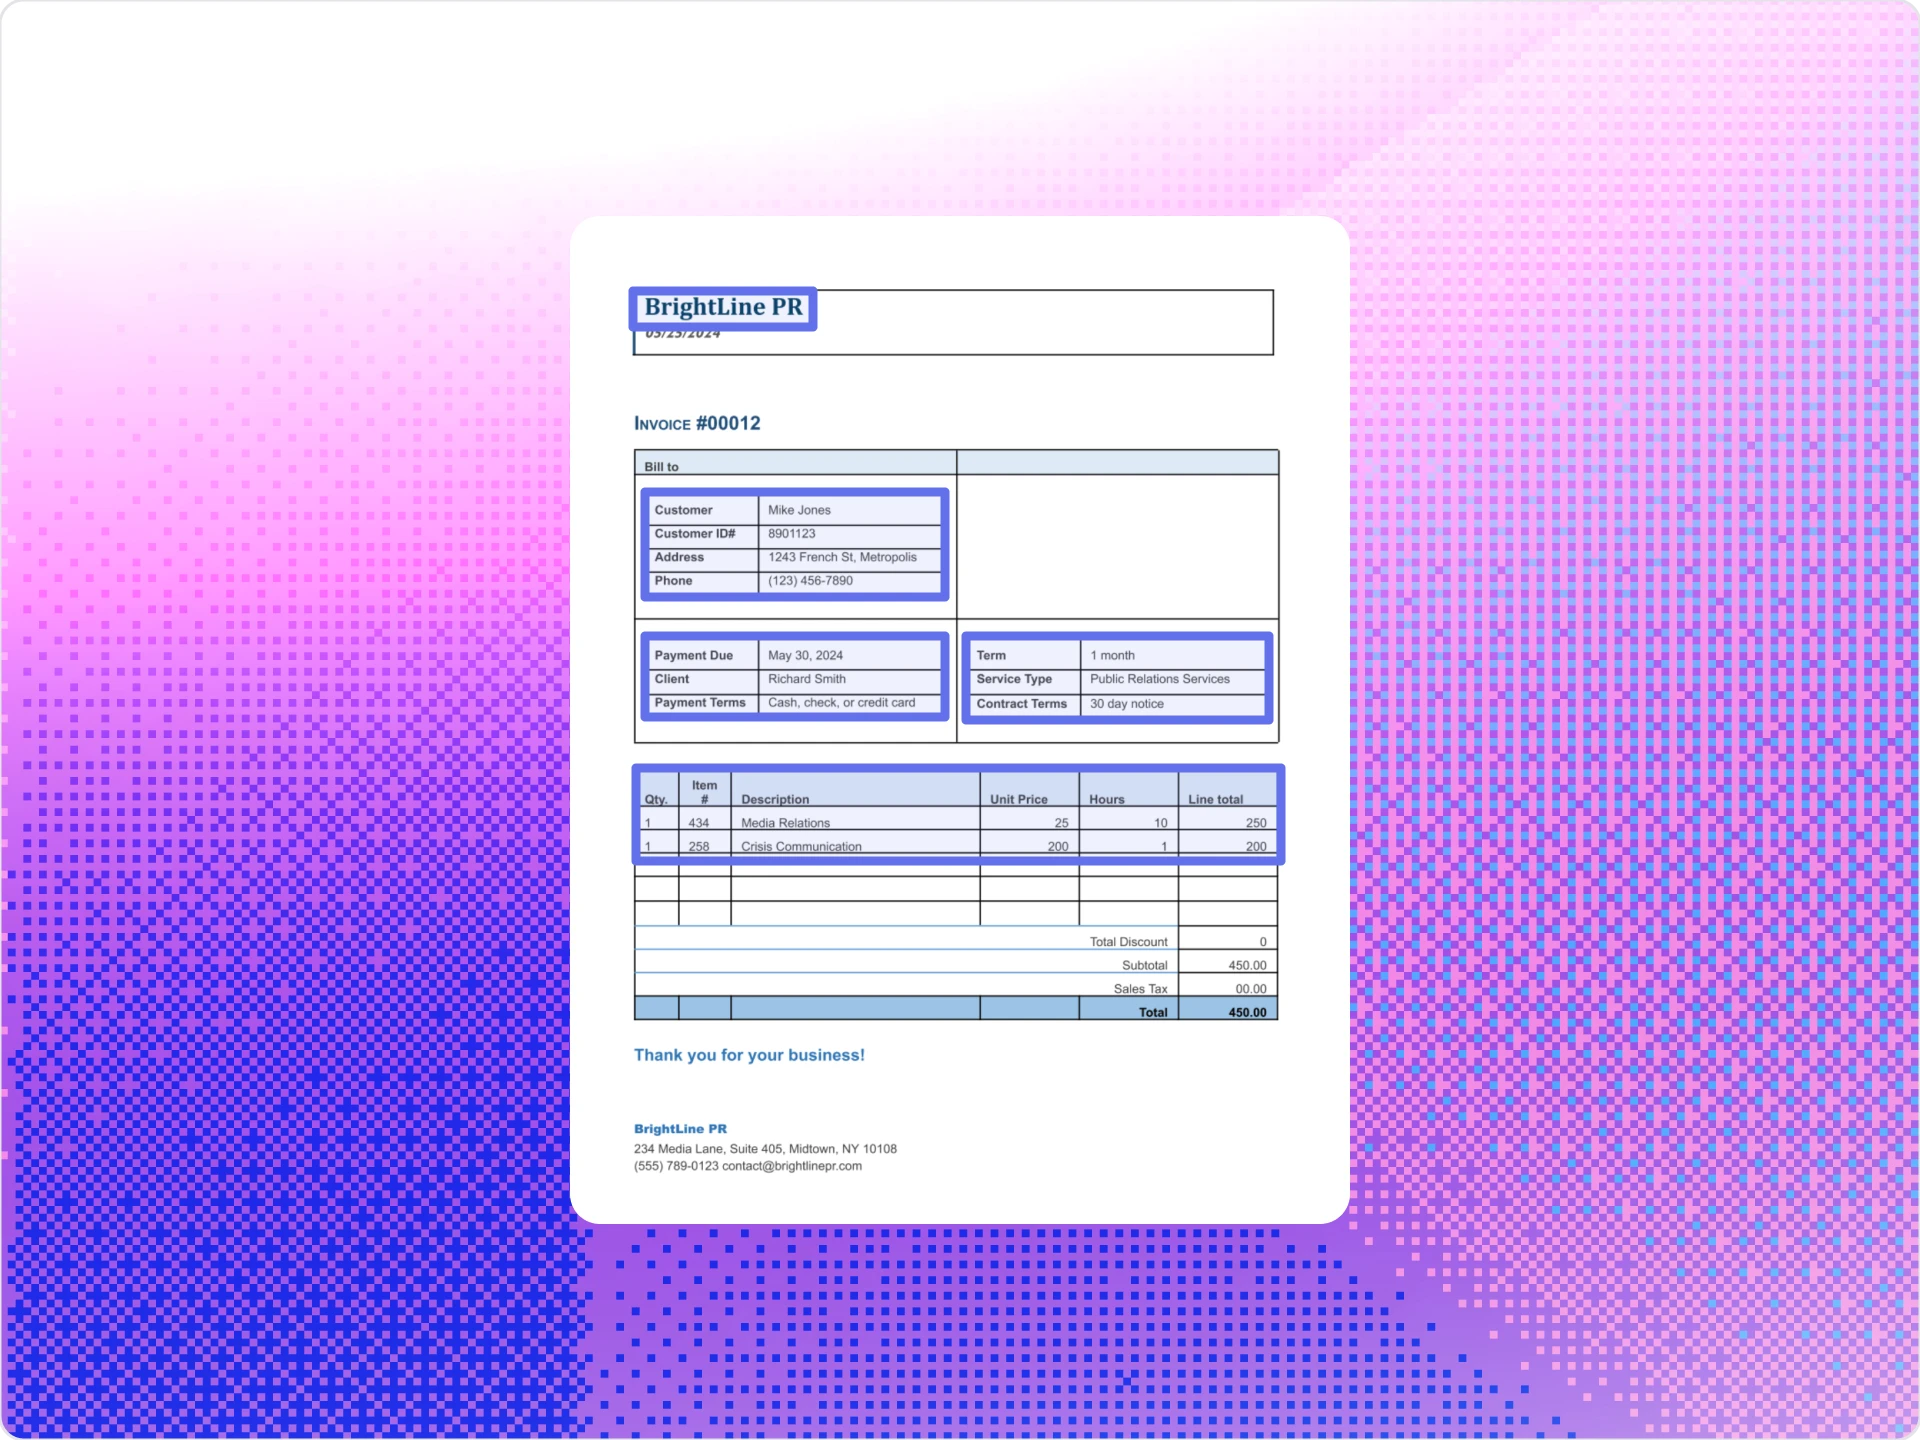
GNN trained on PDF internals, not pixels
Graph Neural Network reads vector structure directly. No image rendering pipeline, no OCR uncertainty. By parsing primitives instead of pixels, we preserve 100% of the table semantics and document hierarchy.
CPU-only. Sub-second. Self-hosted
No GPU. No cloud dependency. Runs anywhere Python runs. PyMuPDF extracts structured data in milliseconds on standard instances, cutting infrastructure costs by up to 250x.
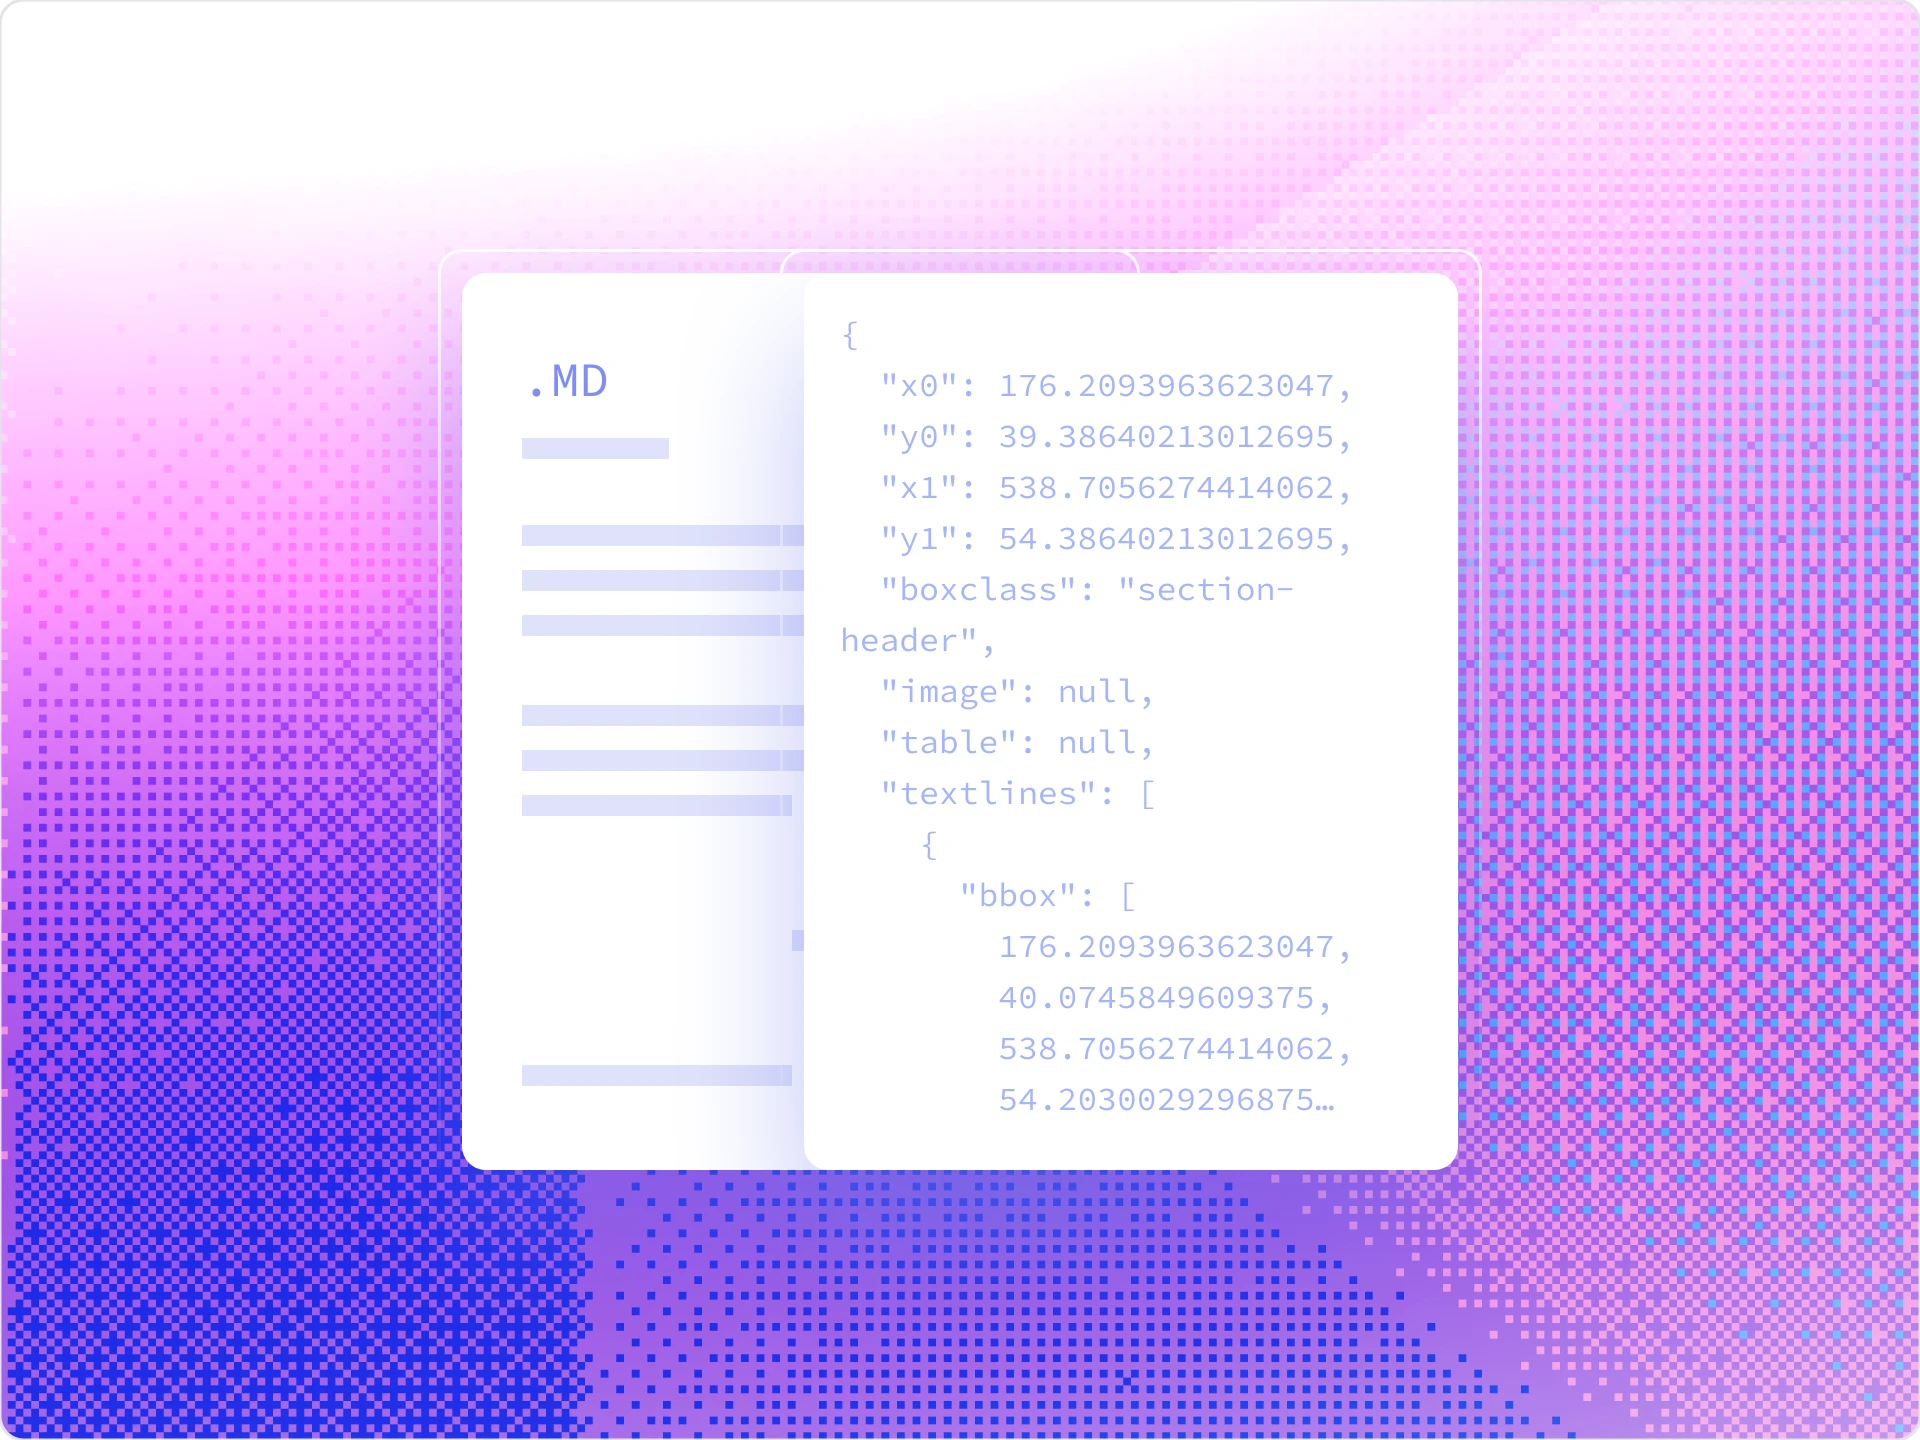
Native Markdown, JSON, & LlamaIndex Ready
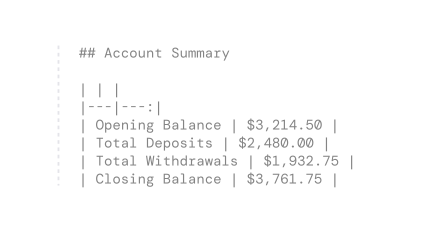
One import brings your documents straight into the RAG pipeline. Support for natural reading order, table conversion, and image extraction is baked in, with direct output to Markdown for vector embeddings.
Up and Running in One pip install
With PyMuPDF 2.0, GNN-trained parsing, CPU-only performance, and LLM-ready output all ship in one package. No separate installs, no juggling versions, just one pip install.
PyMuPDF Office
Everything in PyMuPDF, plus Office (Word, Excel, PowerPoint) and HWP support.
The PyMuPDF Family


Start building in minutes
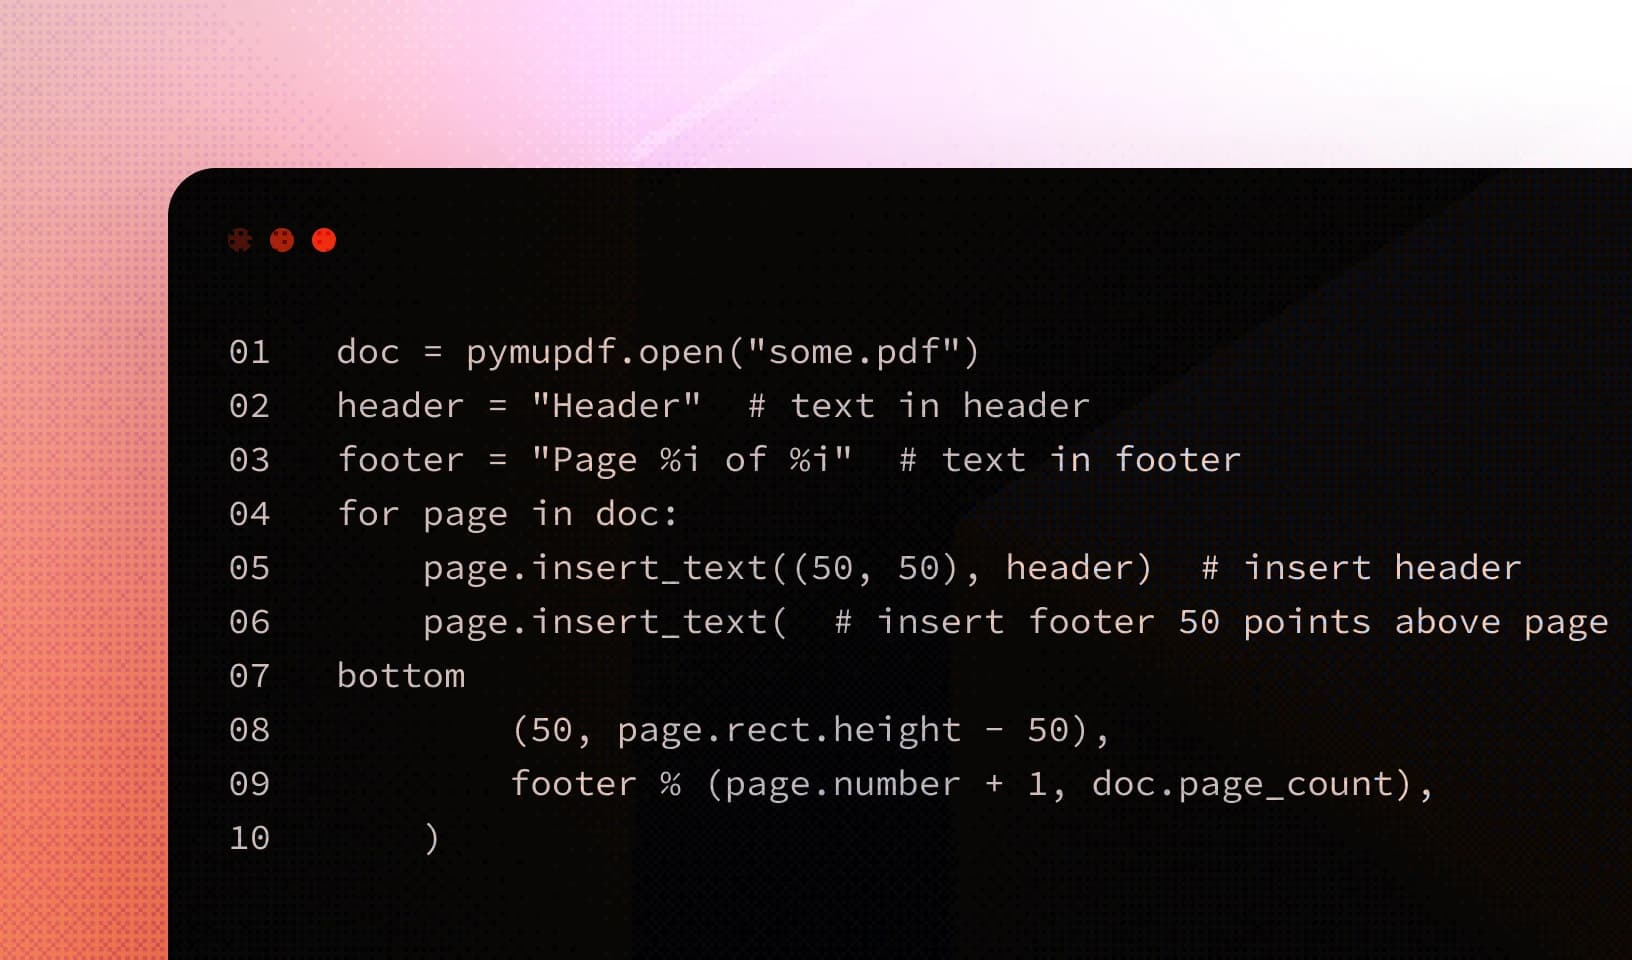
Real Python examples, straight from the docs.
Latest from PyMuPDF
Join Our Forum
No marketing speak, no sales pitches. Just developers helping developers ship document processing features faster.
VISIT FORUM
Start Working with Your Documents
Process PDFs with a library built around the document itself: its content, structure, and layout.